Showing posts with label api. Show all posts

Sunday, January 18, 2009

jQuery 1.3 upgrade & selector bug

I've just upgraded my website to jQuery 1.3. First thing that broke was the attribute selector. This was well documented in the jQuery 1.3 Release Notes - Upgrading as well as in the documentation. So this was easily fixed.

Another problem I had was with a selector matching <select> tags, such as

$('.size select')

For some reason it is no longer matching the <select> tag, but it's <option> tags instead. There is plenty of buzz about how jQuery switched to Sizzle.js selector engine and all the performance gains. I have not found any information pointing to the change that causes by selector bug. Navigating to the parent node solved the issue for me, but it's more like an ugly hack rather than expected behavior.

$('.size select').parent()

Anybody else noticed this problem?

Wednesday, November 19, 2008

Track 404 with Google Analytics

For many of us it is important as well as interesting to see where our customers go, which pages they visit. Tracking the pages is quite simple with Google Analytics. However the question is: "How do you track the pages that do not exist?"

If you configure your server or web application to handle 404 error - page not found (I strongly recommend you do) you will have a template page that is displayed every time the user navigates to an invalid URL - a page that does not exist.

So, how do we do this? How do we track our customers that somehow got lost and landed in a location that does not exists, at least not as a valid location that would provide them with the information that they expected.

It's quite easy. If you search for more information you may come across Google Analytics blog post Tracking 404 Pages, which is now outdated as the new ga script is recommended instead of old urchin. The best source for the answer is Google documentation itself. Simply follow these instructions.

<script type="text/javascript">
    var pageTracker = _gat._getTracker("UA-xxxxx-x");
    pageTracker._trackPageview("/404.html?page=" + document.location.pathname + document.location.search + "&from=" + document.referrer);
</script>

This code sends a virtual pageview of "/404.html?page=[pagename.html?queryparameter]&from=[referrer]" to your account, where [pagename.html?queryparameters] is the missing page name and referrer is the page URL from where the user reached the 404 page.

Then simply look for /404.html in your Top Content report.

Saturday, June 02, 2007

Google Developer Day 2007 in Sydney

Google Developer Day 2007I attended Google Developer Day in Sydney this week. The main page describes the content of the sessions in Sydney. It also links to related video records that can be viewed at YouTube.

The event was well organized. Originally, this was meant to be a 100 people event. However due to its popularity, the event was fully booked within 20 minutes after the registration opened. Later Google decided to change the venue to Australia Technology Park and were able to accommodate all people from the waiting list.

Google Developer Day 2007Google Developer Day 2007

One of the biggest announcements was Google Gears (BETA). It is available for Windows, Mac and Linux. Google Gears is an open source technology for creating offline web applications. As published in Sydney Morning Herald:

The Gears technology promises to give Google a better platform from which to go after Microsoft's very lucrative Office franchise.

Here is a blog post that will get you started with Gears.

Another announcement of the day was Google's purchase of Panoramio, a website that links millions of photos with the exact location where they were taken.

Google Web Toolkit (GWT) got an upgrade as well. GTW 1.4 Release Candidate is a major upgrade to the Google’s open-source framework for writing AJAX web applications in the Java programming language. Read more about its features at ZDNet blog post by Ed Burnette: Google Web Toolkit 1.4: "Have to see it to believe it".

Google Web Toolkit had brought Google's AJAX development out of the dark ages and into the 21st century.

said Lars Rasmussen in his AJAX is painful, painful, painful talk.

Also announced was Google Mashup Editor - experimental product, online application to create mashups. It is currently in beta and access is limited to small number of developers during this testing period.

A great combination of Google's APIs are Google Mapplets. They are mini-applications that you can embed within the Google Maps site. Then they can manipulate the map using Javascript calls that are derived from the Google Maps API. The preview maps site also has Street View, which is very cool and was enabled just few days before Google Dev Day.

When we arrived we received a "speedgeeking" card, which listed six URLs of Google mashups. These six sites were presented live on big screens in the lunch area where everybody had a chance to see the products, talk to the authors and cast one's vote. At the end of the day, Property Guru took the prize home.

Google Developer Day 2007

And if it was not Google, there would be no search. I was strongly reminded that Google is the company behind the most popular search engine when I saw this card on the tables.

Google Developer Day 2007 tag

So there you go Google! I blogged and published my photos with GDD07 tag. Go and find me!

Sunday, April 22, 2007

People still don't get String comparison

How many times we have seen String comparison done using == or != operators?! Yet, people still get it wrong.

I have seen some blog posts recently where the authors had a good intention to show a case where hard-coding values went wrong. Unfortunately, they fell into the common mistake of comparison of String references.

So, if you really need to compare two String using == or != make sure you call String.intern() method before making comparison. Otherwise, always prefer String.equals(String) for String comparison.

Fail-fast vs. complete validation

Almost all applications work with data that come from the interaction with humans or other applications. These data, however, may not necessarily meet the requirements of the accepting applications. Data must be validated.

What is validation?

Data entered must pass a set of validation rules in order to be recognized as valid and allowed for further processing.

As an example, lets take a class that has three members: name:String, created:Date and total:int. Our application requires that name is set (not null) and has at least three characters; created is also required and must be a date representing time before now; and total must be a non-negative integer.

There are two common approaches to data validation: fail-fast validation and complete validation.

Fail-fast validation

How it works

If any of the validation rules fails, validation is stopped and data is pronounced invalid and rejected for further processing.

Output

Boolean result that indicates the validity of input data: true for valid, false for invalid.

Pros

It is generally faster than complete validation as first failure terminates the execution of consecutive validation rules. Does not have the over of failure cause reporting.

Cons

Does not provide enough information about the cause of failure.

When to use it

If a simple result: true or false is enough; detailed information about the cause of failure is not required. May be suitable for cases when the source of data cannot correct the data (usually a system without human input).

Example

boolean isValid(String name, Date created, int total)

Data is passed in and boolean result is returned.

Complete validation

How it works

Failure of a validation rule does not stop the validation process. Data is marked as invalid and rejected for further processing after completing whole validation process.

Output

Boolean result that indicates the validity of input data: true for valid, false for invalid. Some form of error collection that contains the information about the causes of validation failure.

For examples see ActionMessages class from Struts framework, Errors class from Spring framework or ErrorCollection class in Atlassian JIRA.

Pros

Provides information about the cause or causes of validation failure. This information can provide the necessary feedback for correcting the input data.

Cons

Slower than fail-fast validation as extra information about causes of validation failure are reported and full set of validation rules is executed independently on the validation result.

When to use it

When a complete set of failure causes is required. The causes of failure may provide hints to the user entering the data about how to correct the data.

Example

void validate(String name, Date created, int total, ErrorCollection errorCollection)

Data is passed in along with the error collection. Method does not have to return anything (void) as invalid data is indicated by the presence of errors in the error collection.

Conclusion

If the complex validation rule set can be broken down into separate validations per input field, these can be used in order to enhance the user experience (via JavaScript or AJAX) – they can provide a real-time feedback for the data being entered.

Also consider that some cases can involve several other input values in order to make a decision about validity of input data. Such case can for example be a single date value consisting on the values from three input fields (don't do this, it's not a really good way of entering dates)

or conditionally required fields, such as the text area in the next picture is only required to be filled in if "other" is selected.

Both types of validation serve their purpose. Which one you decide to use depends mostly on how much information about data being validated you really need in order to make a decision or to correct it in case of failure.

Tuesday, February 27, 2007

toString() and primitive values

How can one convert a primitive value such as integer or boolean to String object?

Well, there are many ways. There is one way that I have seen so many times:

String strValue = new Integer(intValue).toString();

or

String strValue = new Boolean(booleanValue).toString();

Similarly new instance can be created and the toString() method invoked on classes such as Integer, Long, Float, Double, Byte, Short and Boolean.

The problem is that a boxed primitive is allocated just to call toString() method on it. Each time this is executed, a new instance, new object is created. However, object creation is not necessary and can be avoided. Creating object just for one method call is highly inefficient as the object can be garbage collected on the consecutive line.

The solution

It is more efficient to use the static form of toString() method, which takes the primitive value as a parameter.

String strValue = Integer.toString(intValue);

or

String strValue = Boolean.toString(booleanValue);

Side note

...and please don't do the following

Integer number = ...
String strValue = Integer.toString(number.intValue());

If you already have an instance of integer wrapper class, simply call

String strValue = number.toString();

Thursday, February 22, 2007

Log4J Logger vs. Category

Logging is the practice of recording sequential data. This is also a low-tech method of debugging and in some cases also the only way as the proper debugging tools may not be always available or applicable. Logging in Java can range from simple System.out.println() statements to usage of sophisticated logging frameworks.

At the time of writing there are several logging frameworks for logging in Java available. There is a popular and probably the most widely used Log4J framework. Younger brother of Log4J is the Java's Logging API that became part of Java SE in version 1.4. See How does the Java logging API stack up against log4j for comparison. The are many other logging frameworks: SimpleLog, jLo, Protomatter Syslog, etc.

There are also several frameworks that enable abstraction from logging frameworks, also known as logging bridges (Apache Commons Logging, log-bridge). These allow switching between logging frameworks. These and many others can be found at Open Source Logging Tools in Java at java-source.net.

Log4J was one of the early logging frameworks that gained popularity and is present in many source code bases. In some cases you could encounter usage of Category class rather than Logger. If you work or worked on projects that are built on top of relatively young frameworks, you may not even know that Category class exists as its natural habitat is in old Java code. I hadn't known that Category class existed until I saw it one day. I saw it in a place where I would usually use Logger class. Since that day I kept reminding myself to look at it and see what's different from Logger class and why would one use it.

So what is the difference between Category and Logger classes? The Java documentation in Category class states

This class has been deprecated and replaced by the Logger subclass. It will be kept around to preserve backward compatibility until mid 2003.

Logger is a subclass of Category, i.e. it extends Category. In other words, a logger is a category. Thus, all operations that can be performed on a category can be performed on a logger. Internally, whenever log4j is asked to produce a Category object, it will instead produce a Logger object. Log4j 1.2 will never produce Category objects but only Logger instances. In order to preserve backward compatibility, methods that previously accepted category objects still continue to accept category objects.

Then the following example shows how Category was used and how Logger should be used.

// Deprecated form:
Category cat = Category.getInstance("foo.bar");

// Preferred form for retrieving loggers:
Logger logger = Logger.getLogger("foo.bar");

And that's it. That's all you have to do to replace Category with Logger (apart from renaming the variable).

The documentation also says

There is absolutely no need for new client code to use or refer to the Category class. Whenever possible, please avoid referring to it or using it.

Why is this important? The plan is that from Log4J version 1.3 Category class will be removed! What can we do to prepare our code for Log4J 1.3? Well Preparing for Log4J version 1.3 has it all spelled out. It's worth to read if you want to understand all implications this upgrade may have. I just shamelessly paste the steps here:

  1. Never refer to the Category class directly, refer to Logger instead.
  2. Do not invoke the deprecated Category.getRoot method. Invoke Logger.getRootLogger method instead.
  3. Do not invoke the deprecated Category.getInstance(String) method. Invoke Logger.getLogger(String) method instead.
  4. Do not invoke the deprecated Category.getInstance(Class) method. Invoke Logger.getLogger(Class) method instead.
  5. Never refer to the Priority class, refer to Level class instead.
  6. Do not invoke the deprecated Category.setPriority(Priority) method. Invoke Logger.setLevel(Level) method instead.
  7. Do not invoke the deprecated Priority.toPriority(int) method. Invoke Level.toLevel(int) method instead. The same holds true for the other variants of the Priority.toPriority method.
  8. Never refer to the deprecated Priority.FATAL, Priority.ERROR, Priority.WARN, Priority.INFO, Priority.DEBUG fields. Refer to the Level.FATAL, Level.ERROR, Level.WARN, Level.INFO, Level.DEBUG fields instead.

  9. If you confiugure appenders programmatically, do not forget to invoke the activateOptions method of an appender after you have instantiated it and set its options.

and as the above mentioned document says

For 99.99% of users, this translates to the following string find-and-replace operations:
  1. Replace the string "Category.getInstance" with the string "Logger.getLogger".
  2. Replace the string "Category.getRoot" with the string "Logger.getRootLogger".
  3. Replace the string "Category" with the string "Logger".
  4. Replace the string "Priority" with the string "Level".

Happy logging!

Monday, October 02, 2006

Web APIs

Web APIs are sexier that desktop APIs. Having an API allows the external developers to access your data or your services in a smart way. They can they use your data or services in ways you would not imagine.

Currently it is very popular to use the data with mapping APIs. At the moment the Google Maps have the best and most detailed images of Australia. Microsoft competes with Virtual Earth, they have good images, good maps, but a very restrictive licensing. Yahoo! Maps has also good images and also gives a choice of Flash or JavaScript. They also provide an option of a static image. The downside of Yahoo! Maps is the lack of mapping information.

Another popular category of APIs is Search. Search APIs can provide cache access, spell-checking, content analysis and much more. Amazon's API offers search on prices, images, customer reviews and affiliate sales.

A good resource for Web APIs is ProgrammableWeb, which acts as an encyclopedia of available APIs and how people use them.

Mashups are novel UI that enhance your data, e. g. by combining your local data with mapping information. Chicagocrime.org – one of the first map mashups was built prior to Google’s API being made public. It’s not all about maps – TagTV, Viral Video Chart, BlueOrganizer, Salesforce Adwords.

There are two general types of APIs: interfaces (maps) and data types (the rest). For example Google Maps are very simple to include; just drop in the script, add four lines of JavaScript and you are done. The other APIs are simply a request to a web resource via HTTP. XML is often used to return the result, though JSON is becoming more popular. These can also be called directly from JavaScript using the XMLHttpRequest object.

The current limitations several. You are limited to the functionality that the provider makes available, unless you screen scrape. There are also concerns with automated collection of personal data, licenses and the changes in terms of use (what will you do if Google Maps is no longer available). We also need to standardize. There are some APIs available that abstract the mapping API access and allow you to switch between Google Maps, Yahoo Maps, etc. Cross domain AJAX is also a security risk. Images, CSS and JavaScript can be loaded from other damains, but HTML or XML can not. A workaround could a proxy server, but this could be a bottleneck if not cached. JSON-P is another alternative, currently supports GET requests, but fails silently if you get the API URL wrong.

In the future we can see ContextAgnosticXmlHttpRequest, enhanced JSON – JSONRequest. Web APIs are all about work we do not have to do. So open your data, offer an API, let the others do the work!

Wednesday, September 27, 2006

First element in the List

Imagine this scenario. You are working on an existing application. There is a framework used. One of the benefits that this framework gives you is retrieving and processing parameters coming from the client, let's say a web application. The framework gives you all parameters as a List. Now in this particular case you always get only one parameter, but is it enclosed in the List. How do you get it out efficiently?

The intended method would be described: Get the list of parameters and if not empty, return first element in the list otherwise return null. The code was looked similar to this:

1 public E getSingleParam(List params) {
2 E param = null;
3 if (params != null && params.size() >= 1) {
4 param = params.iterator().next();
5 }
6 }

This code works fine but it has several points for improvement. First is how the code at line 3 expresses the intention of check whether the list of parameters is not null and not empty, specifically the later. List interface defines boolean isEmpty() method that is in most cases more efficient to run than getting the size and comparing it to 0 (greater than) or 1 (grater than or equal). That is if the list implements an internal flag for its "emptiness" state or has an internal counter as opposed to re-counting its elements. In the worst case scenario the efficiency will be the same as getting the size and comparing it with 0. In that case isEmpty() method is still a nice convenience method to call and should be preferred before the size() > 0 alternative. Another reason is that it speaks for itself. All we need to know is whether there are any elements in the list or not. Getting the size should be used to for other purposes (e.g. calculating the width of the table column when displaying the results in a tabular form – 100% / size()).

1 public E getSingleParam(List params) {
2 E param = null;
3 if (params != null && !params.isEmpty()) {
4 param = params.iterator().next();
5 }
6 }

The second point of making the code to perform better and to make it easier to read is the line 4. On this line we are getting the first element of the list. As shown in the example above, this is an inefficient way as we construct an Iterator only for the purpose of one iteration. Constructing new objects and disposing of them is usually expensive and should be avoided. A better way is to access the element directly, such as:

1 public E getSingleParam(List params) {
2 E param = null;
3 if (params != null && !params.isEmpty()) {
4 param = params.get(0);
5 }
6 }

This way no new objects are constructed (no Iterator). Another difference between the two is the exception that could be possibly thrown. The exception would be thrown if we did not have the previous check or in the case of concurrent modification of the list which is very unlikely in this case. The exception thrown in first case would be a NoSuchElementException. In the second way, an IndexOutOfBoundsException would be thrown. Both of them are runtime exceptions and do not have to be declared. In this case getting one exception or the other should not make any difference.

Tuesday, August 22, 2006

Tricky instanceof operator

Let's start with a little puzzle.

Object obj = ...
System.out.println(obj instanceof Object);

How do you initialize the obj in order to print "false"?

Well, aren't all possible Java objects instances of Object? To answer this question one must understand how instanceof operator works. The answer is that it would print "true" for any Object. The only way to make it false is not to give it an object, give it a null reference.

The tricky bit about instanceof operator can be that if object on the left side is null, the condition evaluates to false. Therefore there is no need for null check after a class cast as in the following example.

public boolean equals(Object o) {
if (o instanceof MyClass) {
MyClass mc = (MyClass) o;
if (mc == null) // never null
return false;
else
return ... // compare members of mc
}
return false;
}

This can be simplified as shown in the following code snippet

public boolean equals(Object o) {
if (o instanceof MyClass) {
MyClass mc = (MyClass) o;
return ... // compare members of mc
}
return false;
}

So the moral if this excercise is that instanceof operator works as you would expect with objects, and returns false when given a null.

And remember that equals() method is probably the only reasonable place for instanceof operator. If you do it elsewhere and use it to create an alternative flow (e.g. if-else, switch) it is a bad smell and should be replaced with polymorphism. Read more about Swich Statement code smell and Polymorphism

BTW the previous example was not a very nice example of how to implement equals method, so do not copy it ;-) Usually we would do something like this

public boolean equals(Object o) {
if (o == null) return false;
if (o == this) return true;
if (!(o instanceof MyClass)) return false;
MyClass mc = (MyClass) o;
return ... // compare members of mc
}

Wednesday, August 16, 2006

Programmable Web and GoogleMaps Fligh Simulator

Today I came across an iteresting website: ProgrammableWeb - because the world's is your programmable oyster. In their words:

ProgrammableWeb is where you can keep-up with the latest mashups, what's new and interesting with Web 2.0 APIs, and the Web as Platform in general. The core of the site is the blog and the 3 dashboards: Home, Mashups and APIs. All dashboards are updated daily.
It's worthwhile having a look at API part. And this is how I found

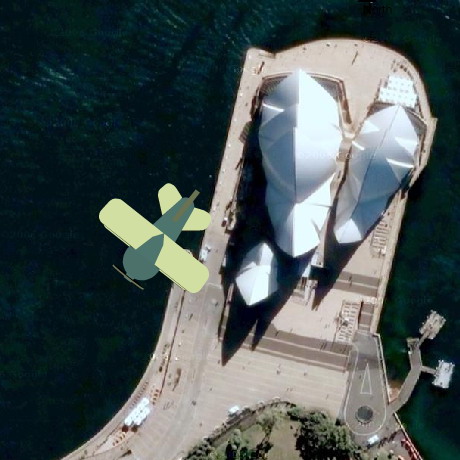
Quite nice app, good fun exploring the world without being scared of terrorism! And as you can see I had a few successful flights over the Sydney Opera House. But be careful! Do not fly too low, you can crash!

Friday, June 09, 2006

Java call stack - from HTTP upto JDBC as a picture

Peter Thomas created an image consisting of several screens worth of call stack profiler data. Then he divided it into sections that represent the layers or frameworks used.

Take a look at his picture here , or get the zoomable PDF version here.


Creative Commons License This work is licensed under a Creative Commons Attribution-NonCommercial-ShareAlike 2.5 License.